Databricks & Data Engineering
Databricks Lakehouse Architecture: A Practical Enterprise Blueprint
A high-level guide to designing reliable Bronze, Silver, and Gold data layers with governance, observability, and cost control across AWS and Azure.
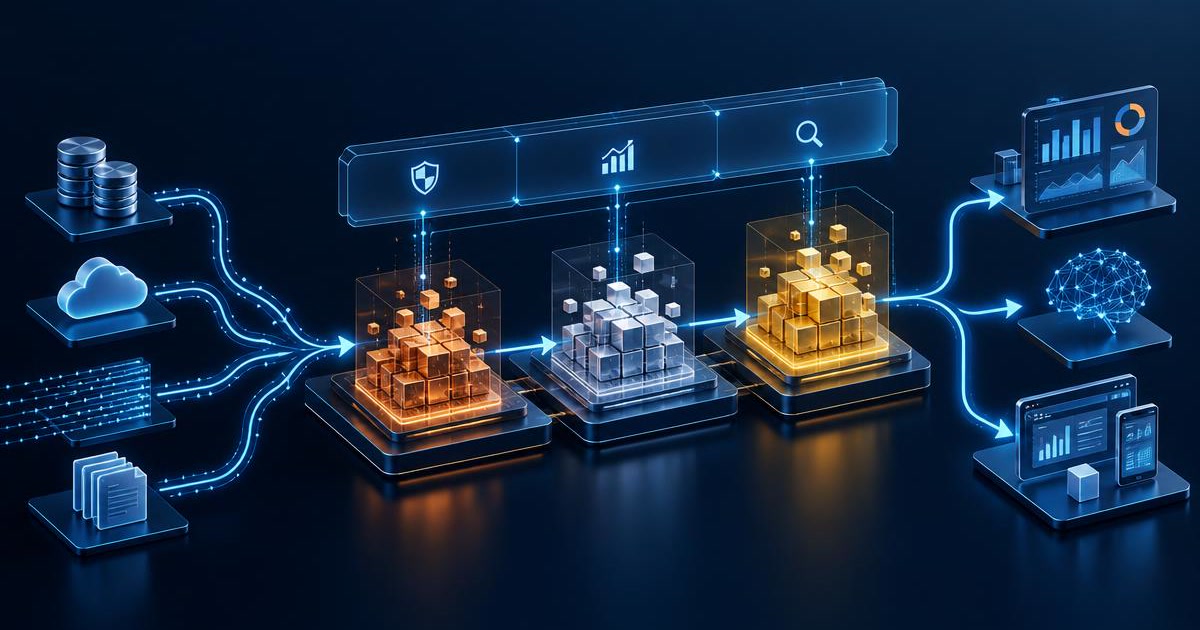
A production lakehouse is not simply a collection of notebooks and tables. It is a managed path from raw operational data to trusted business decisions, with quality, security, lineage, and cost controls designed into every stage.
The high-level blueprint
A sound design separates data by its level of refinement. Databricks describes this multi-layer pattern as medallion architecture: Bronze preserves source fidelity, Silver produces validated and reusable data, and Gold serves business-ready products. The separation lets teams improve quality progressively without losing the original record.
Bronze
Land faithfully
Ingest files, database changes, APIs, and event streams with source metadata and minimal transformation.
Silver
Validate and conform
Apply schemas, deduplicate records, quarantine failures, standardize keys, and model reusable entities.
Gold
Serve outcomes
Publish aggregates and domain data products designed for BI, applications, analytics, and machine learning.
Governance and observability sit across every layer rather than becoming a final gate. Access policies, ownership, lineage, freshness, quality signals, and spending data should travel with each product from ingestion to consumption.
Design ingestion around change, not just volume
Start by classifying each source: append-only files, mutable databases, software APIs, or event streams. This determines whether the pipeline needs scheduled batches, change data capture, continuous streaming, or a hybrid pattern.
- Batch fits predictable source extracts and reporting windows where minutes or hours of latency are acceptable.
- Streaming fits events, telemetry, fraud signals, and operational decisions where new records must appear continuously.
- Incremental processing should be the default for large tables; avoid re-reading complete history when only a small partition changed.
Every ingestion path should be replayable and idempotent. If a job fails halfway through, the next run should recover without silently duplicating records or skipping a source interval.
Make data quality an executable contract
Quality checks belong in the pipeline, not in a spreadsheet maintained after an incident. Define the contract for each important dataset: required fields, accepted values, uniqueness, referential integrity, freshness, and volume expectations.
A useful failure policy has three outcomes:
Reject data that would corrupt a critical result, quarantine records that can be investigated separately, and warn when a non-critical threshold drifts.
Capture rejected records with the rule, timestamp, pipeline version, and source reference. This creates an auditable path to correction and helps owners distinguish a source-system issue from a transformation defect.
Governance must be part of the architecture
Organize data around business domains and ownership rather than mirroring every source system forever. A governed catalogue should show who owns a table, where it came from, which transformations created it, who can access it, and how long it should be retained.
- Apply least-privilege access at catalogue, schema, table, row, or column level as required.
- Separate development, test, and production environments with controlled promotion.
- Classify sensitive fields and record access to regulated or business-critical data.
- Give every Gold product a named business owner and a defined service expectation.
Observability: monitor the data and the platform
A successful job is not proof of correct data. Operations teams need two views: platform health such as compute utilization, failures, duration, and spending; and data health such as freshness, completeness, schema changes, and quality-rule outcomes.
Pipeline signals
Run status, duration, throughput, retries, backlog, dependency delays, and service-level objectives.
Data signals
Freshness, row-count variance, null rates, duplicates, schema drift, and quarantined records.
Alerts should identify the affected business product and likely cause, not simply announce that a notebook failed. Route them to an accountable owner and maintain a short recovery runbook for critical paths.
AWS and Azure: preserve the pattern, adapt the controls
The logical lakehouse pattern is portable, but identity, networking, storage, encryption, and private connectivity must follow the selected cloud. On AWS, align workspaces with IAM roles, object storage policies, and private networking. On Azure, align them with managed identities, storage access, private endpoints, and the organization’s tenant model.
Keep cloud-specific setup in automated infrastructure and configuration rather than embedding it in transformation logic. This makes environments reproducible and reduces the risk of inconsistent manual settings.
Build cost control into workload design
Cost optimization starts with architecture. Match compute to workload behavior, turn off idle resources, use job-scoped capacity for scheduled processing, and avoid moving or transforming data without a consumer requirement.
- Tag workloads by team, environment, product, and cost centre.
- Set budgets and alerts before production volume arrives.
- Track cost per pipeline or data product alongside reliability metrics.
- Review inefficient queries, unnecessary recomputation, file sizes, and retention regularly.
Optimize for total business value, not the lowest compute bill. A cheaper pipeline that misses the reporting window or produces untrusted data is not an efficient system.
Implementation checklist
Questions to settle before implementation
Do we need streaming for every pipeline?+
No. Use streaming when the decision genuinely requires continuous updates. A well-designed incremental batch is often simpler and more economical for scheduled reporting.
Should consumers query the Bronze layer?+
Normally no. Bronze is the recoverable system record. Most users and applications should consume validated Silver entities or purpose-built Gold products.
When should governance begin?+
At architecture time. Retrofitting ownership, access, lineage, and classification after production creates avoidable rework and risk.
How do we know the platform is ready for production?+
Critical pipelines need tested recovery, observable service levels, clear ownership, controlled deployment, capacity planning, and agreed quality thresholds.
Plan your lakehouse
Turn the blueprint into a delivery roadmap.
EdgeWave can assess your sources, workload priorities, governance needs, and cloud setup, then define a practical Databricks implementation plan.
Book an architecture workshopOfficial references
- EdgeWave: Databricks Banking Case Study: From Siloed Data to Trusted Decisions
- EdgeWave: Odoo Customization: A Practical Guide to Building ERP Around Your Business
- Databricks: What is the medallion lakehouse architecture?
- Databricks: Best practices for Lakeflow pipelines
- Databricks: Design an observability strategy
- Databricks: Cost optimization best practices