Hospitality Data Engineering
Hotel Booking & Revenue Analytics: A Data Engineering Case Study
How batch ETL pipelines, dimensional data models, data-quality checks, and Power BI dashboards turn scattered hotel booking data into trusted occupancy, ADR, and RevPAR insights.
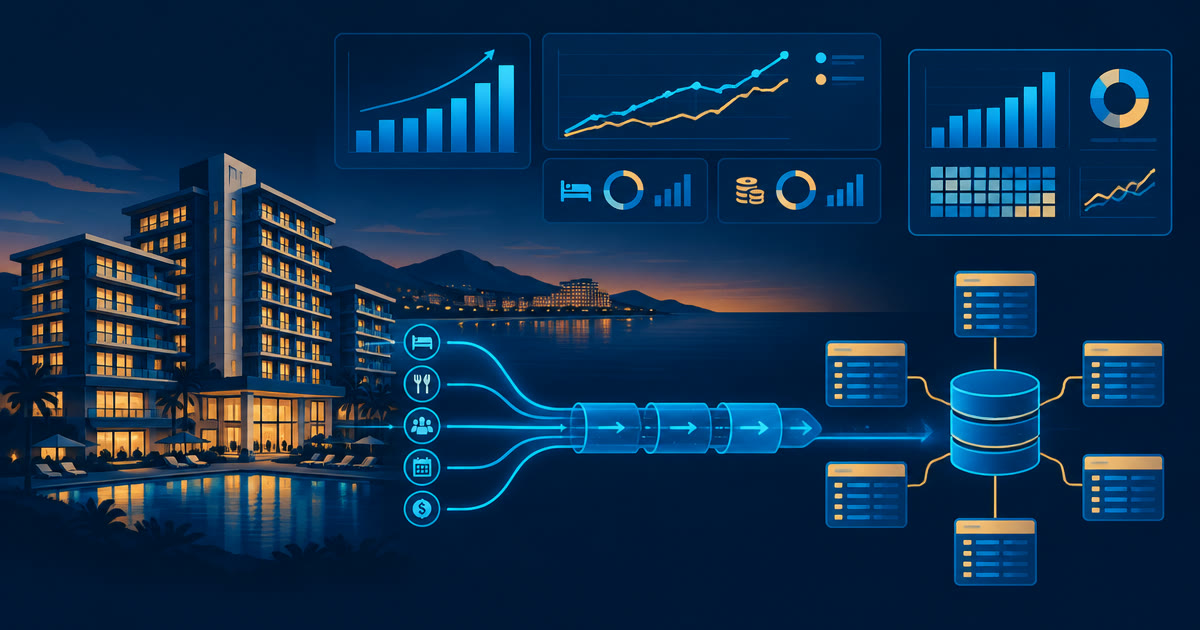
Hotels generate data every second: bookings, cancellations, payments, room inventory, and guest profiles. But raw data scattered across booking systems, spreadsheets, and payment gateways cannot answer the questions revenue managers actually ask. Data engineering is the discipline that turns this raw material into clean, reliable, analysis-ready datasets.
Why data engineering matters in hospitality
Every hotel group eventually asks the same questions: Which properties have the highest cancellation rates, and why? What is our Revenue per Available Room trend this quarter? Which booking channels bring the most profitable guests?
None of these questions can be answered directly from source systems. Booking engines, property management systems, channel managers, and payment gateways each store a fragment of the truth, in different formats, with different keys. Data engineering builds the bridge: pipelines that collect the fragments, models that give them structure, quality checks that make them trustworthy, and reporting layers that make them useful.
Scattered sources
Bookings, customers, rooms, and payments lived in separate systems with no shared identifiers or consistent formats.
Duplicate records
The same guest appeared under multiple spellings and emails, inflating customer counts and distorting segmentation.
Manual reporting
Revenue and occupancy reports took days of spreadsheet work, so decisions were always made on stale numbers.
No trust in data
Without quality checks, invalid booking dates and missing values quietly corrupted every downstream report.
Solution architecture at a glance
The platform follows a simple, proven flow: ingest from source systems, transform through batch ETL pipelines, store in a dimensional data warehouse, enforce data quality, and serve reporting datasets to Power BI.
Sources
Booking engine exports, property management data, customer records, room inventory, and payment transactions.
Batch ETL (Python + SQL)
Scheduled pipelines ingest, cleanse, standardise, and deduplicate every dataset before it reaches the warehouse.
Dimensional warehouse
Fact tables for bookings and payments; dimension tables for customers, rooms, properties, and dates.
Data quality gate
Automated checks for duplicates, missing values, and invalid booking dates run on every load.
Power BI dashboards
Occupancy rate, cancellation rate, ADR, and RevPAR — refreshed daily, drillable from group to property to channel.
Step 1 — Batch ETL pipelines with Python and SQL
The first engineering task was building reliable batch pipelines that run on a schedule and prepare every dataset for analytics:
- Ingestion: scheduled batch jobs pull booking, customer, room, and payment datasets from each source system into a raw landing area, preserving the original records for audit.
- Cleansing: inconsistent date formats, currency values, and free-text fields are parsed and corrected into standard types.
- Standardisation: customer names, room types, rate plans, and property codes are unified across all sources so the same thing is always called the same thing.
- Deduplication: duplicate customer and booking records are matched and merged using keys such as email, phone number, and booking reference.
Python handles the flexible transformation logic; SQL handles set-based cleansing and deduplication close to the data. This combination keeps pipelines both maintainable and fast.
Step 2 — Dimensional data modeling with a star schema
The heart of the platform is a dimensional model designed for analytics rather than transactions. Measurable events go into fact tables; the descriptive context goes into dimension tables.
Fact tables
- fact_bookings — booking amount, nights, channel, status, cancellation flag
- fact_payments — payment value, method, date, settlement status
Dimension tables
- dim_customer — deduplicated guest profiles and segments
- dim_room — room types, capacity, and amenities
- dim_property — hotels, locations, and brands
- dim_date — calendar, season, weekday, and holiday attributes
This star schema makes queries fast and lets analysts slice revenue by property, room type, channel, season, or customer segment without writing complex SQL. It also supports multi-property analytics out of the box — one model serves a single hotel or a fifty-property group.
Step 3 — Orchestration and data-quality checks
Pipelines are orchestrated on a daily schedule so dashboards are always fresh. But freshness without correctness is worthless, so every run passes through automated quality gates:
- Duplicate detection: each load is scanned for repeated booking references and customer keys before data is published.
- Missing value validation: bookings without a customer, room, or payment link are flagged and quarantined.
- Invalid date checks: check-out before check-in, impossible stay lengths, and misdated historical bookings are caught automatically.
Failed checks are logged and alerted before bad data can reach a report. This single discipline — never letting untrusted data through — is what makes leadership actually believe the dashboards.
Step 4 — Power BI dashboards and the KPIs that matter
The final layer delivers the metrics hotel leadership runs the business on. Reporting datasets are purpose-built for Power BI, so dashboards load fast and stay consistent with the warehouse.
| KPI | What it tells you |
|---|---|
| Occupancy Rate | Percentage of available rooms sold — demand and pricing health |
| Cancellation Rate | Revenue risk and booking-channel reliability |
| ADR (Average Daily Rate) | Average revenue per sold room — pricing effectiveness |
| RevPAR (Revenue per Available Room) | The industry's core profitability metric — ADR multiplied by occupancy |
Dashboards support drilling from group level down to a single property, room type, or booking channel — so a dip in RevPAR can be traced to its root cause in seconds instead of days.
Business outcomes
Reporting in minutes, not days
Automated pipelines and pre-built reporting datasets replaced manual spreadsheet work, freeing the revenue team to act on numbers instead of assembling them.
One trusted source of truth
Deduplicated customers, standardised properties, and quality-gated bookings mean every team debates decisions — not whose numbers are right.
Early risk detection
Cancellation-rate trends by channel and season surface revenue risk early enough to adjust pricing, policies, and channel mix.
Data-driven pricing
ADR and RevPAR trends by property and room type give revenue managers the evidence to price confidently through high and low seasons.
Key takeaways — the use of data engineering in hospitality
- Data engineering is the foundation. Dashboards are only as good as the pipelines behind them — invest in ingestion, cleansing, and modelling first.
- Dimensional modelling makes analytics fast and flexible. A star schema lets the business ask new questions without re-engineering the platform.
- Data quality is non-negotiable. One duplicate booking inflates revenue reports; quality gates protect trust in every number.
- The pattern travels. The same ETL + modelling + quality + BI foundation applies to retail, healthcare, banking, and manufacturing — only the KPIs change.
Build your analytics platform
Turn your booking data into revenue decisions.
EdgeWave Software designs and delivers data engineering platforms — ETL pipelines, dimensional models, data quality, and dashboards — on Databricks, AWS, and Azure.
Talk to our teamRelated reading and official references
- EdgeWave: Top 5 Big Data Analytics Companies in India (2026)
- EdgeWave: Databricks Lakehouse Architecture: A Practical Enterprise Blueprint
- EdgeWave: Databricks Banking Case Study — From Siloed Data to Trusted Decisions
- EdgeWave: Customer 360° Data Warehouse — E-commerce & Retail Analytics Case Study
- EdgeWave: Real-Time Payment Transaction Processing with Databricks & PySpark
- Microsoft: Power BI overview
- Kimball Group: Dimensional modeling techniques